First part of this series Lapzilla & Qwen3.8-27B Round One
This time around, I am going to use an AI coding tool more like how I use them professionally. This means different models for different purposes and managing context windows. Ollama hosting qwen3.8-27B-mlx will still be used for the local LLM. We’re going to constrain the context window to ~128KB to prevent memory corruption and kernel panics. We’re also going to explicitly set the effort level to medium to fix the extreme slowness caused by the default xhigh and it’s respective reasoning token overhead.
Professionally I use a planning session with a more expensive model. Once that is all set, I tend to switch to lower cost model for the execution session. I used Anthropic’s Fable for the planning. I spend a decent amount of time describing the goals of the project along with the problems and lessons learned from the first round. This produced both the CLAUDE.md, ARCADE-SPEC.md, the PLAN.md, and especially the PROGRESS.md which is the checkpointing in case of a kernel panic. I also included a LESSONS.md for the agentic coding feedback loop.
For context management, I gave instructions to use a subagent for development and testing but never run more than 1 subagent at a time because Ollama running a local LLM is only going to support a synchronous flow. There isn’t enough hardware to support concurrent LLM calls.
Once the plan was all set, I exited claude and restarted with the ollama wrapper.
ollama launch claude --model qwen3.8:27b-mlx
Here’s the usage stats to get to a releasable milestone…
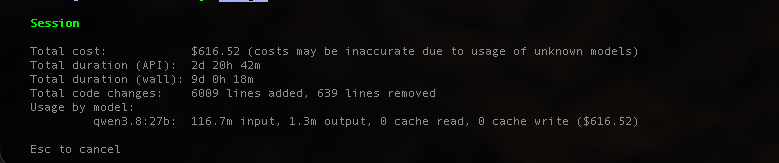
I would let this “cook” while I went and did other things or slept overnight. While it took ~68 hours of linear “compute” time to build, long blocks of time were spent idling while waiting for me to approve something. The qwen model really wants to bias to cat commands with pipings and redirects which the anthropic models don’t do.
Here’s the breakdown using current Anthropic API list pricing (per million tokens, as of September 2026), based on the 116.7M input / 1.3M output tokens:
| Model | Input rate | Output rate | Input cost | Output cost | Total |
|---|---|---|---|---|---|
| Claude Haiku 4.5 | $1 | $5 | $116.70 | $6.50 | $123.20 |
| Claude Sonnet 5 | $2 | $10 | $233.40 | $13.00 | $246.40 |
| Claude Opus 5 | $5 | $25 | $583.50 | $32.50 | $616.00 |
| Claude Fable 5.1 / Mythos 5.1 | $10 | $50 | $1,167.00 | $65.00 | $1,232.00 |
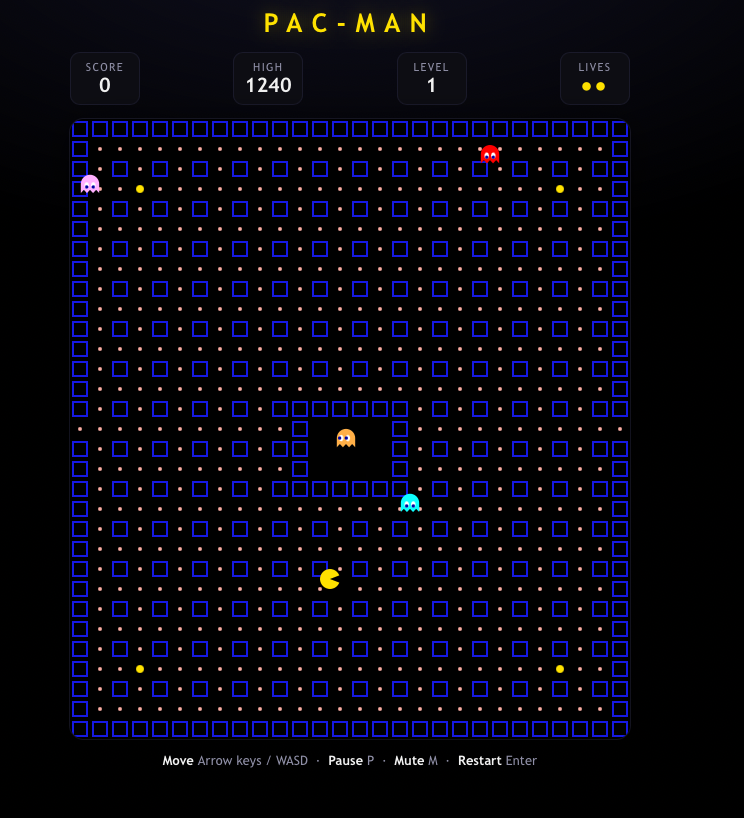
The qwen3.8-27b-mlx model is considered “Opus” level. Excluding the Fable usage for planning, let’s simplify and consider it cost $616 to build this pacman inspired implementation.
Is the qwen3.8-27b hype worth it? In my opinion yes. I have lots things I want to build or experiments I want to run. If I was spending $2K/month on tokens, I’d have a strong incentive to monetize this work. By running the LLM model locally I am essentially trading hardware cost (macbook M5 ultra) for token cost. The more I build the more the hardware costs amortize.
Frontier models for the planning. Local LLMs for the execution and build phases.
Here’s the github repo. Clone it and give it a play.
https://github.com/sean-foley/pacman